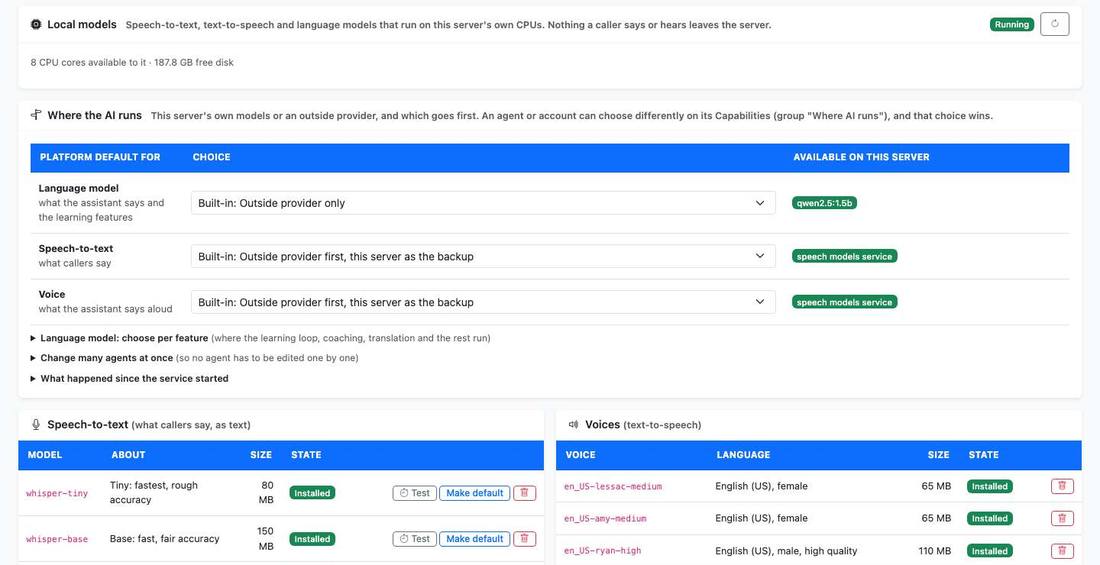
Speech to text, voices and language models can run on the platform's own CPUs, in their own container. Nothing a caller says or hears has to leave your building. Choose per assistant, per group or per account, and switch whenever you like.
Language model, speech to text and voice are chosen separately. The same choice exists for the learning features, texts and coaching, not only live calls.
| Choice | What happens |
|---|---|
| Outside provider only | Every request goes to the provider you configured. |
| Outside first, this server as the backup | Providers first; if one fails or is slow, the platform answers on its own models. |
| This server first, outside as the backup | Own models first; a provider only if they cannot answer. |
| This server only | No outside provider is contacted at all. No key is needed. |
| Follow the account or platform default | One setting for many assistants; override on any one. |
Five Whisper sizes, from a tiny model of about 80 MB to a large one of about 1.6 GB. Pick the size your servers can carry; the screen measures how fast each one is.
18 on-server voices covering English (US and UK), Spanish, French, German, Italian, Portuguese, Arabic, Turkish, Russian, Polish, Dutch, Hindi, Persian and Chinese.
Open-weight models served by an on-server container. Choose the model, and the Test button checks a reply, a follow-up, memory and the judge role before you rely on it.
Knowledge bases can be created with local embeddings, so the documents never go to an outside service to be indexed.
Apply a choice to a whole industry pack, every AI assistant, or one account. Installing an industry pack asks where its AI should run, so you do not edit assistants one by one.
Language detection from the caller's first words, live translation between caller and agent with a glossary, and routing by language skill.
An honest note. On a modest CPU-only server the on-server language model is excellent for learning, texts and background work, but a live conversation is faster on an outside model or a larger server. The first turn of a call is the slow one; later turns reuse what was already processed. You choose per assistant, and the platform falls back automatically.
Tell us which calls must stay on your servers. We will size the models for your hardware and show the fallback working.
Book a demo